Method: Verbalization of Path
EACL 2026 · Oral
1University of Illinois Urbana-Champaign 2Texas A&M University 3Microsoft Research, Redmond
*Equal contribution †Work performed during internship at Microsoft Research
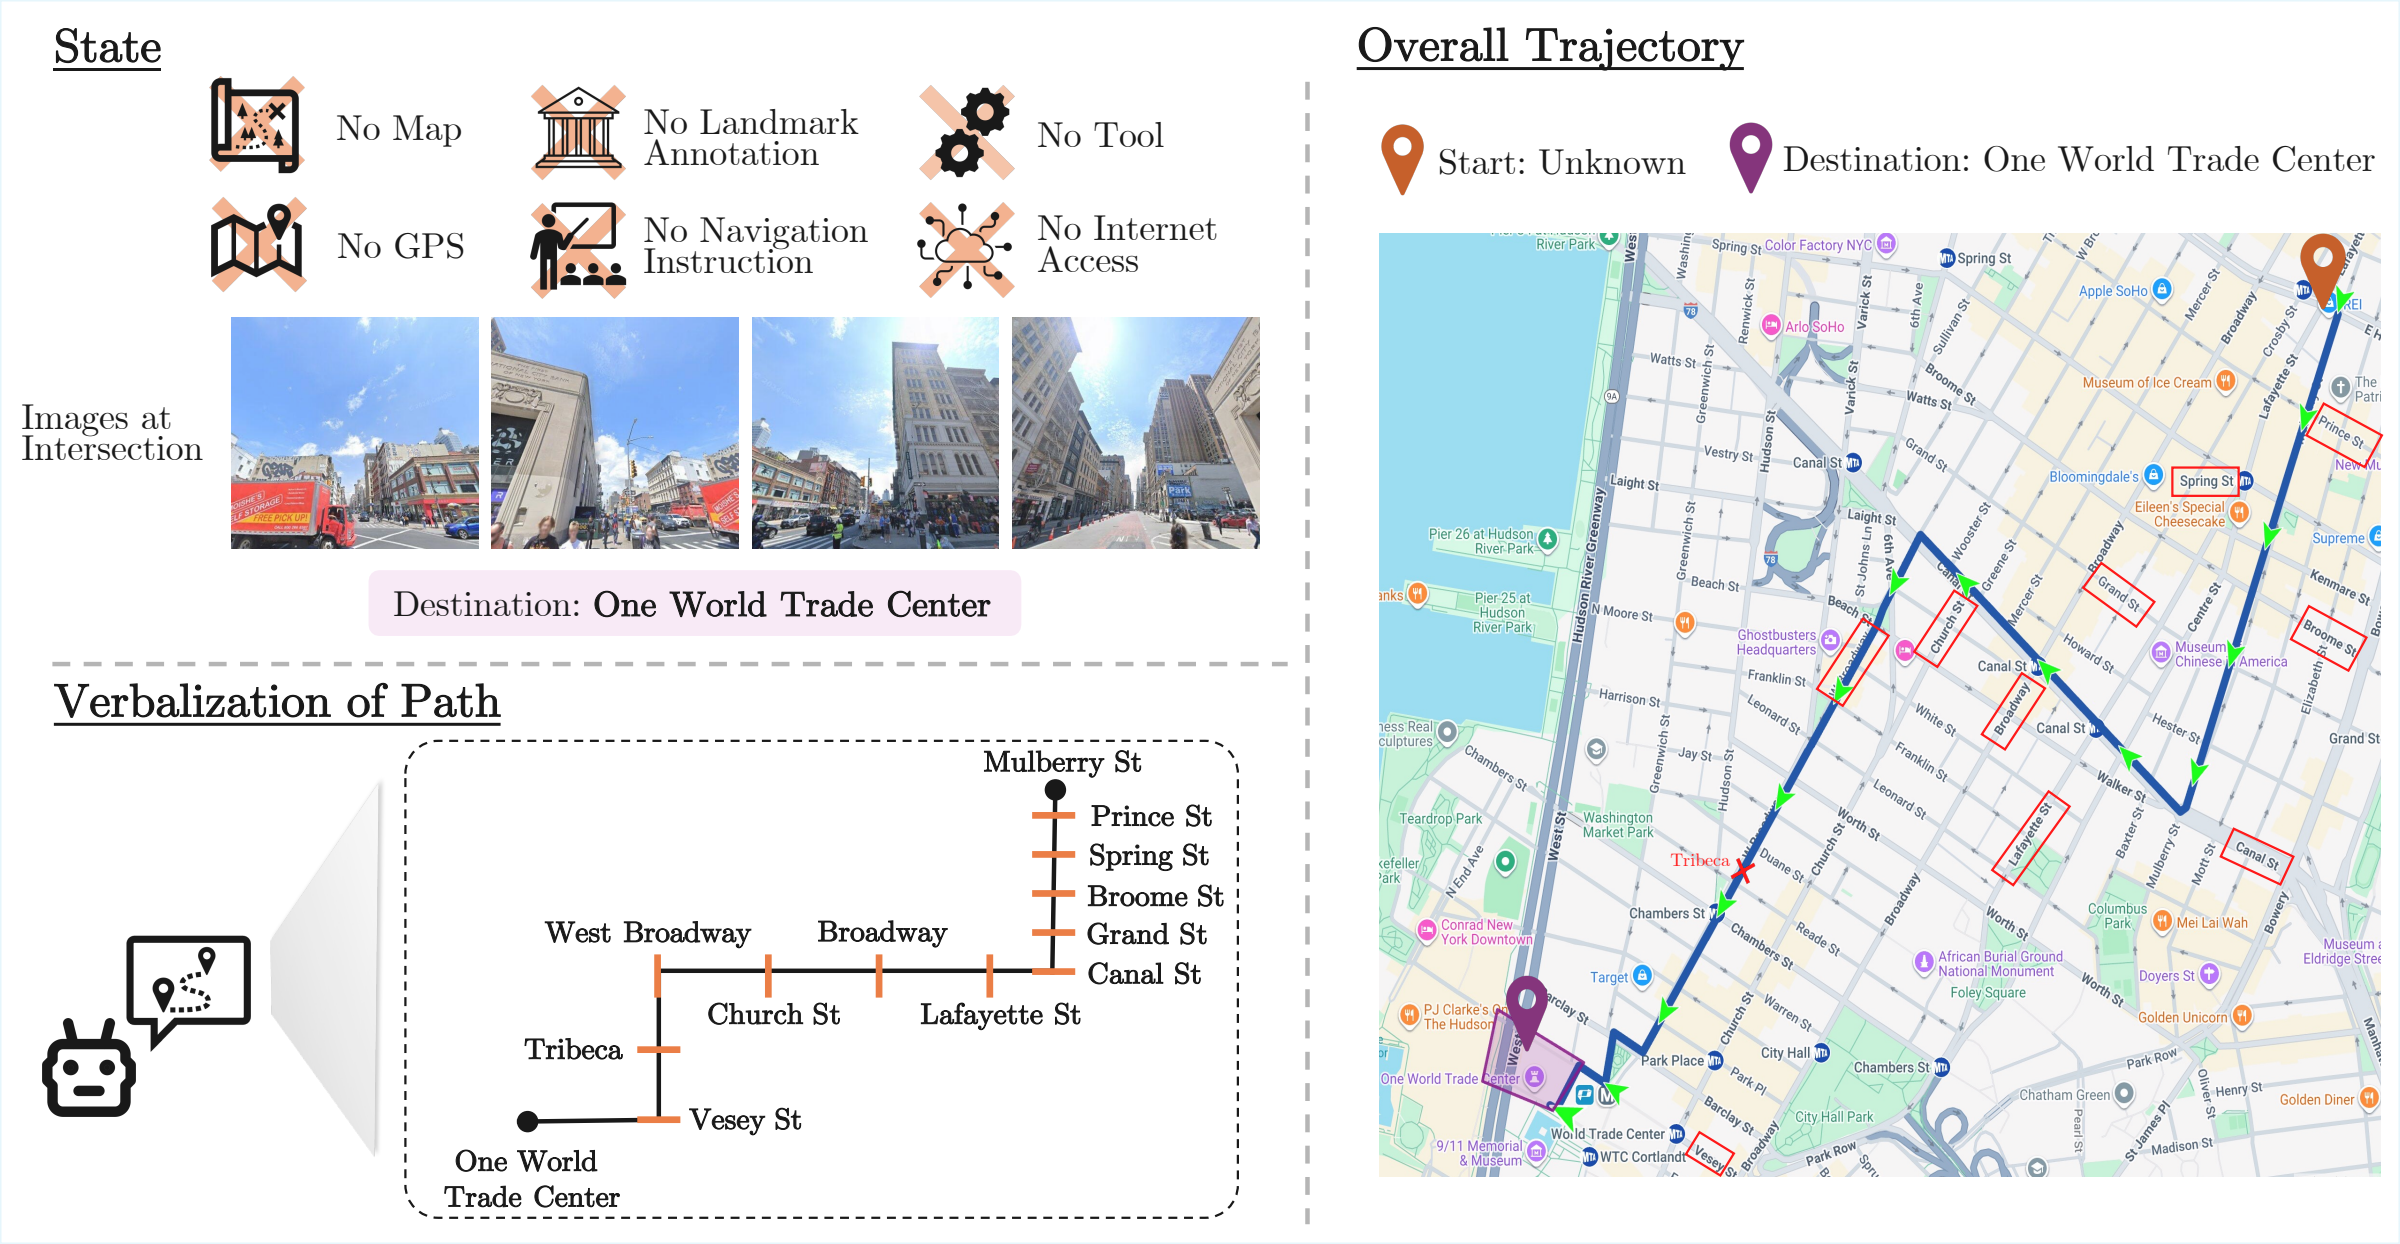
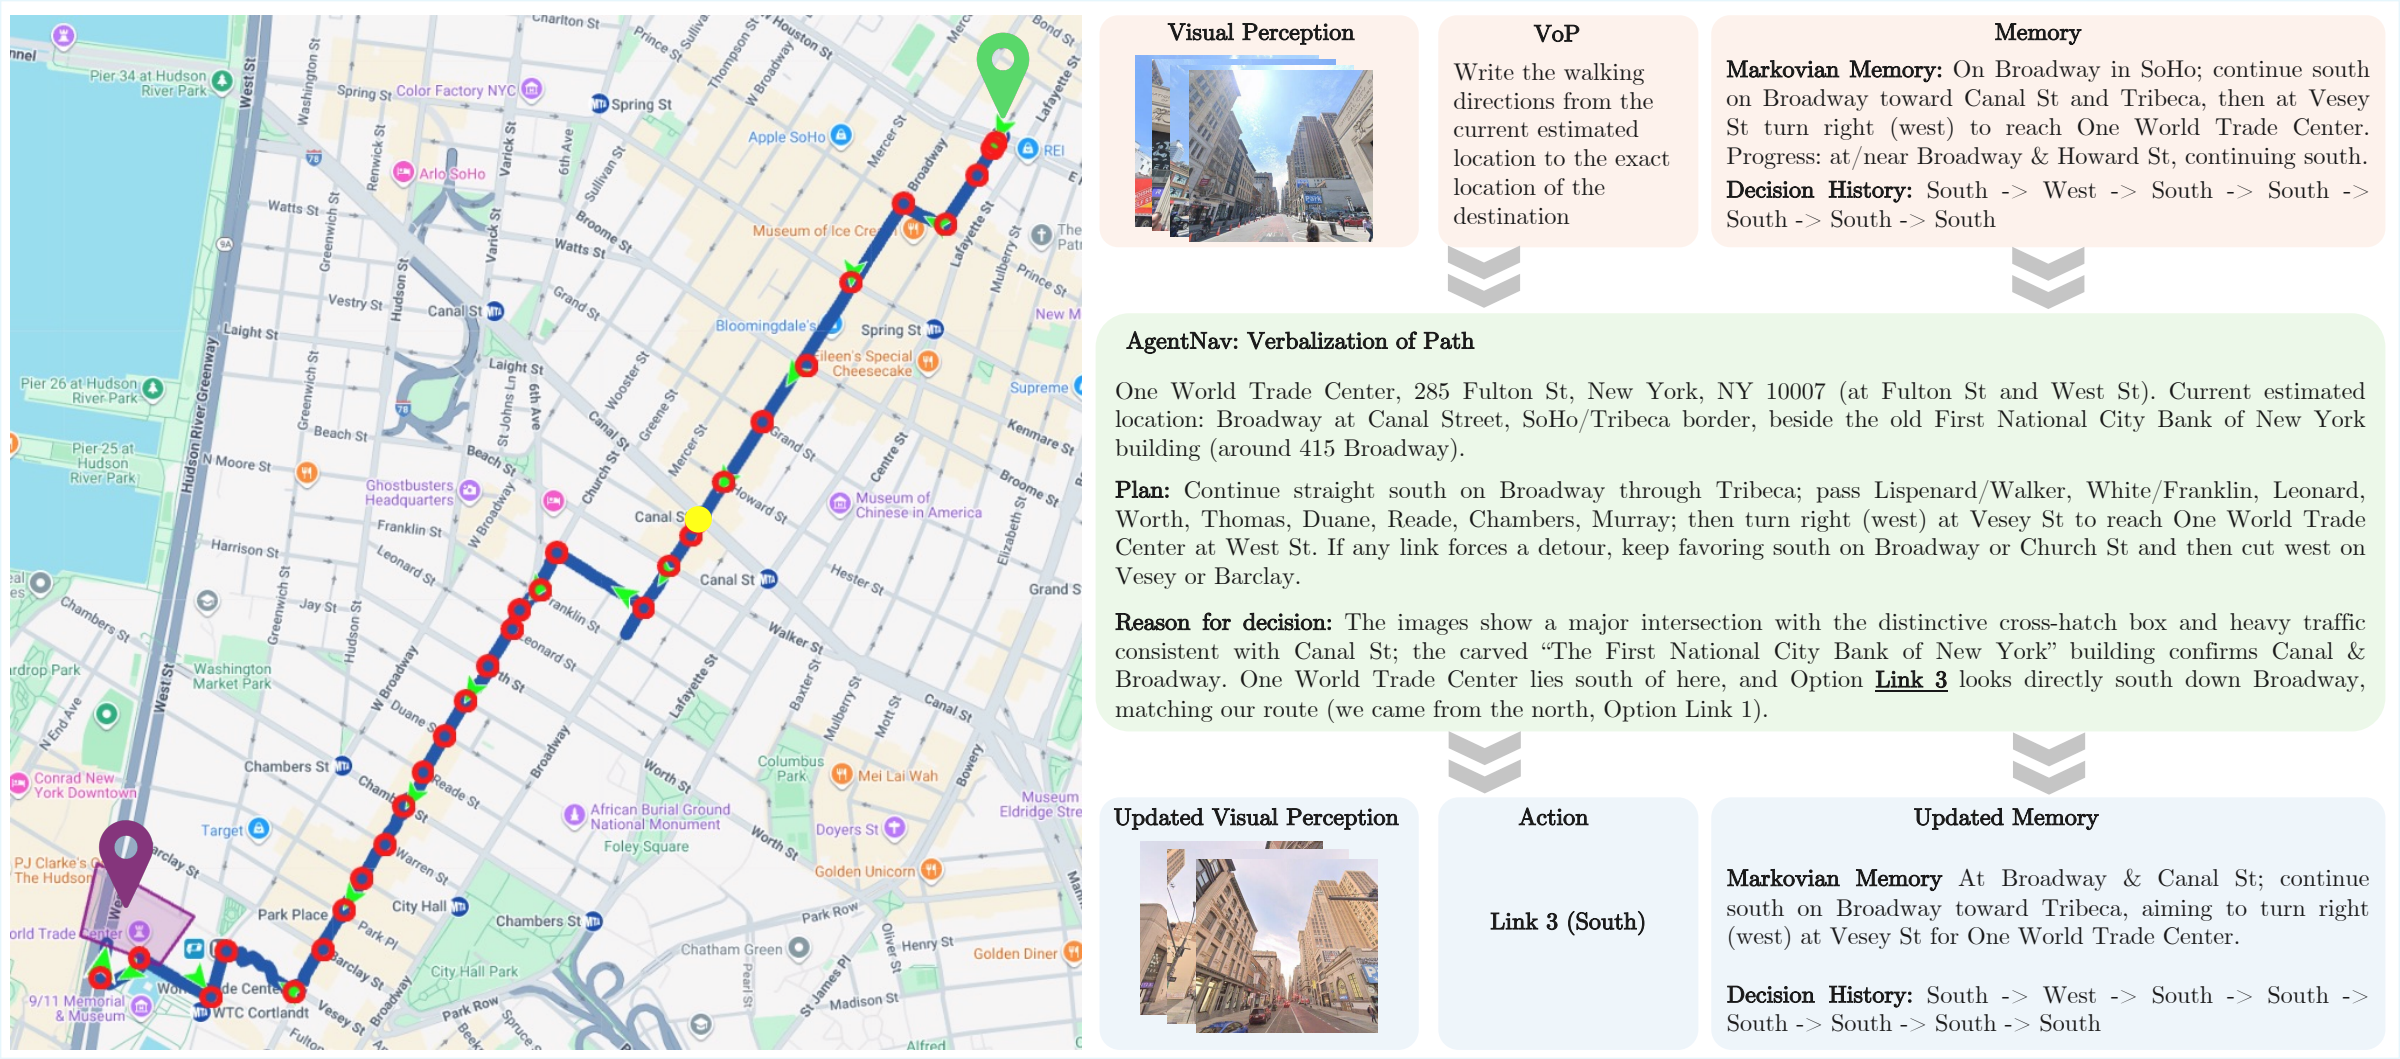
AgentNav with GPT-5 navigating to New York landmarks using only visual observations and internal reasoning.
Leveraging multimodal large language models (MLLMs) to develop embodied agents offers significant promise for addressing complex real-world tasks. However, current evaluation benchmarks remain predominantly language-centric or heavily reliant on simulated environments, rarely probing the nuanced, knowledge-intensive reasoning essential for practical, real-world scenarios.
To bridge this critical gap, we introduce the task of Sparsely Grounded Visual Navigation, explicitly designed to evaluate the sequential decision-making abilities of MLLMs in challenging, knowledge-intensive real-world environments. We operationalize this task with CityNav, a comprehensive benchmark encompassing four diverse global cities, specifically constructed to assess raw MLLM-driven agents in city navigation.
Agents are required to rely solely on visual inputs and internal multimodal reasoning to sequentially navigate 50+ decision points without additional environmental annotations or specialized architectural modifications. Crucially, agents must autonomously achieve localization through interpreting city-specific cues and recognizing landmarks, perform spatial reasoning, and strategically plan and execute routes to their destinations.
Through extensive evaluations, we demonstrate that current state-of-the-art MLLMs and standard reasoning techniques (e.g., Chain-of-Thought, Reflection) significantly underperform in this challenging setting. To address this, we propose Verbalization of Path (VoP), which explicitly grounds the agent's internal reasoning by probing an explicit cognitive map from the MLLM, substantially enhancing navigation success.
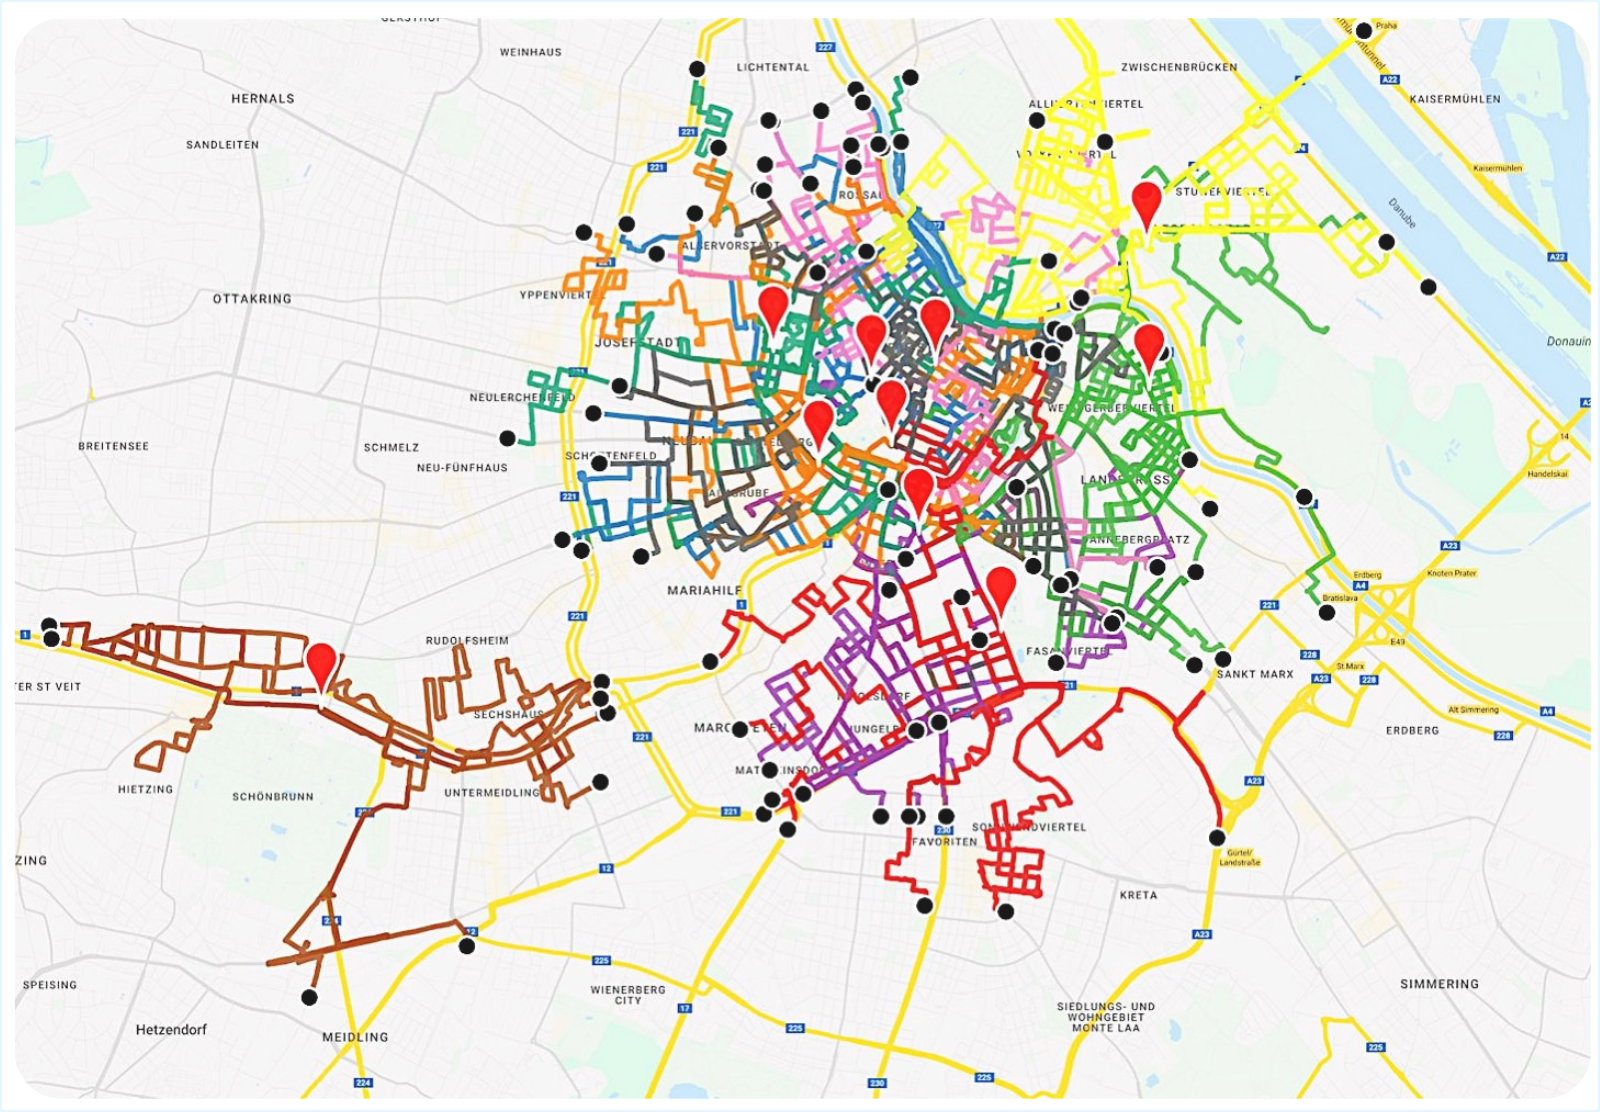
400 navigation tasks across New York, Tokyo, Vienna, and São Paulo. Routes average about 2 km and 50+ decisions. Request dataset access.
| City | Region | Characteristics | Distance (km) | Decision points |
|---|---|---|---|---|
| New York | USA | Grid-based, well-spaced, rich street signs | 1.8 | 44 |
| São Paulo | Brazil | Non-block structure, Portuguese language | 2.0 | 55 |
| Tokyo | Japan | Short sightlines, narrow alleys, Japanese language | 1.9 | 80 |
| Vienna | Austria | Road blocks from rails, German language | 2.1 | 60 |
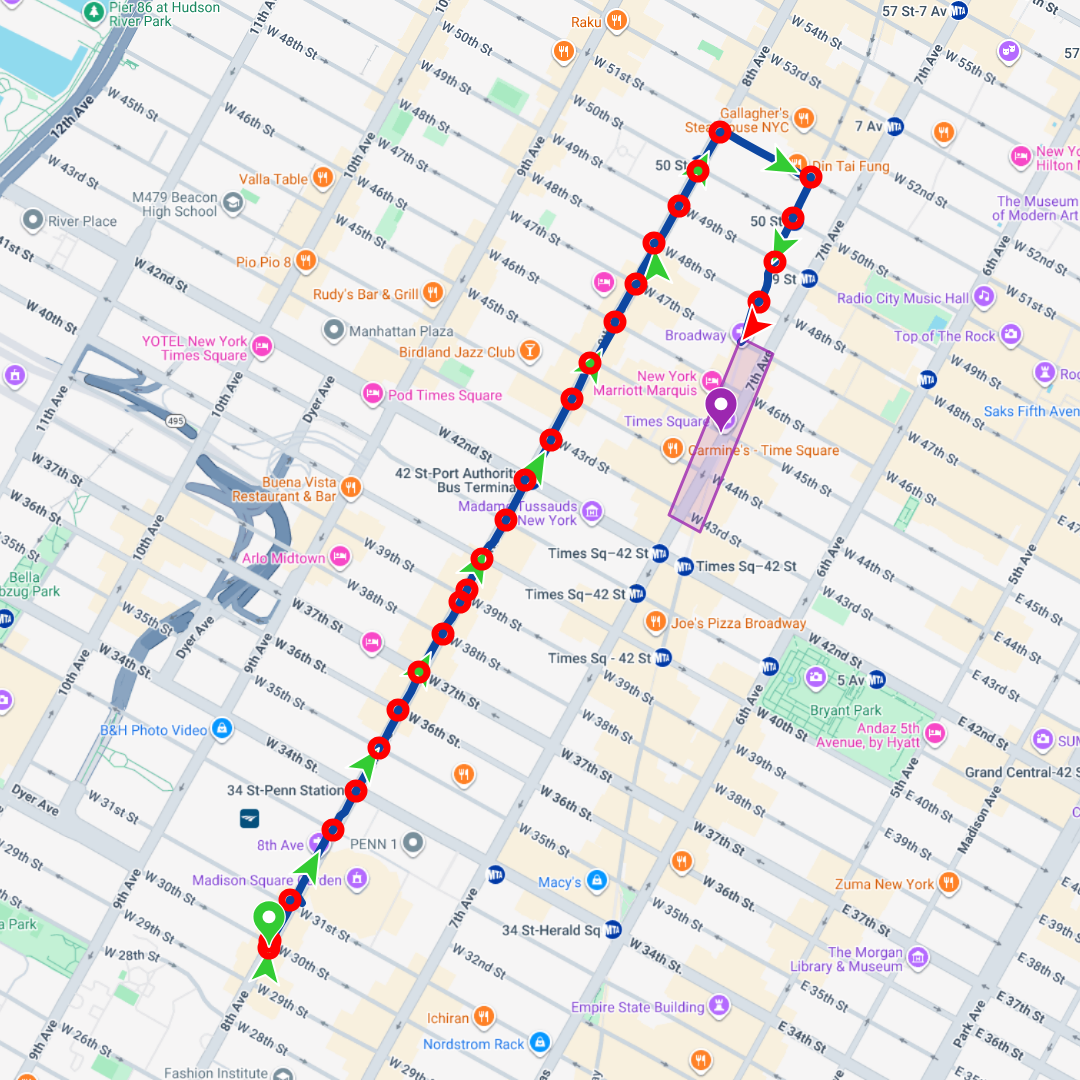
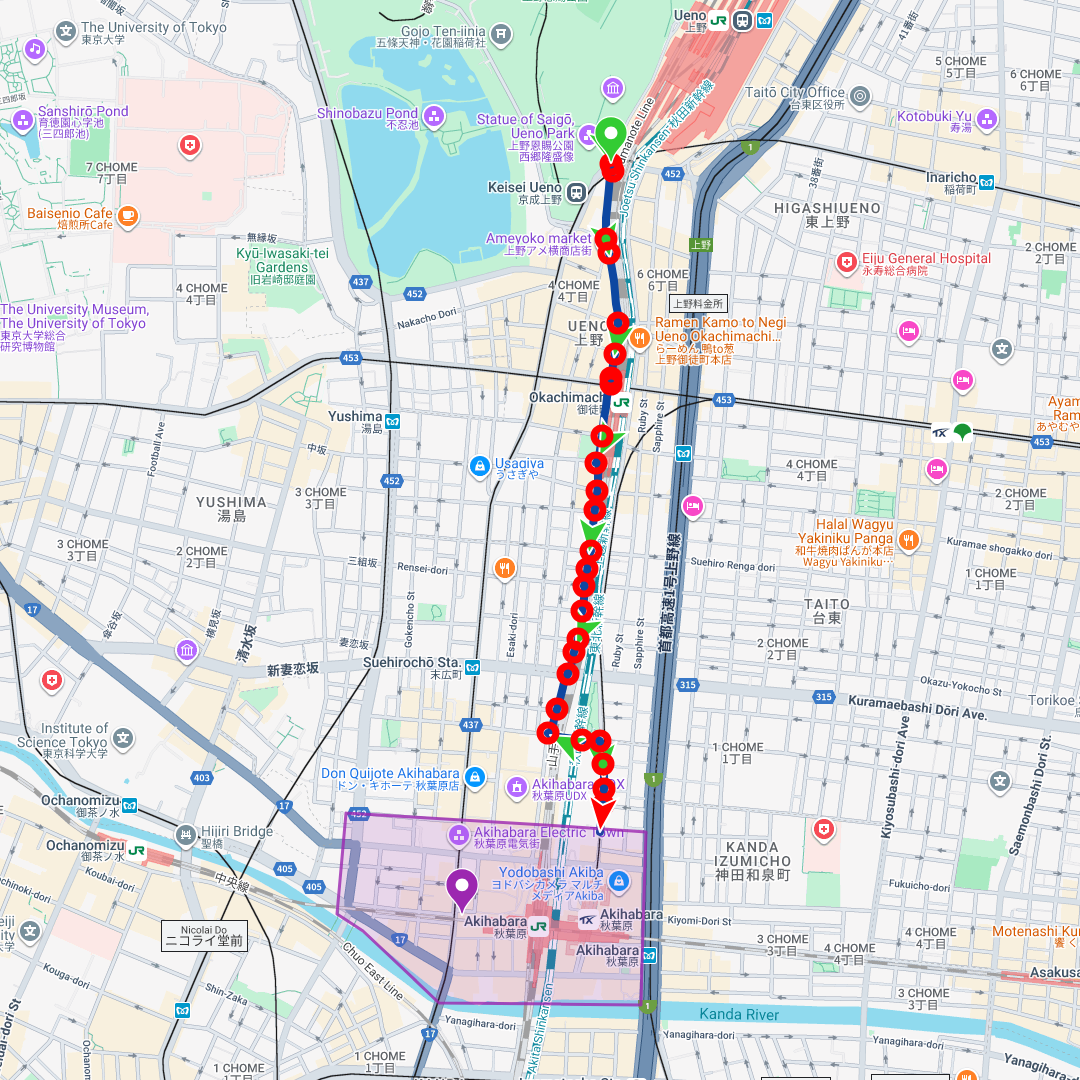
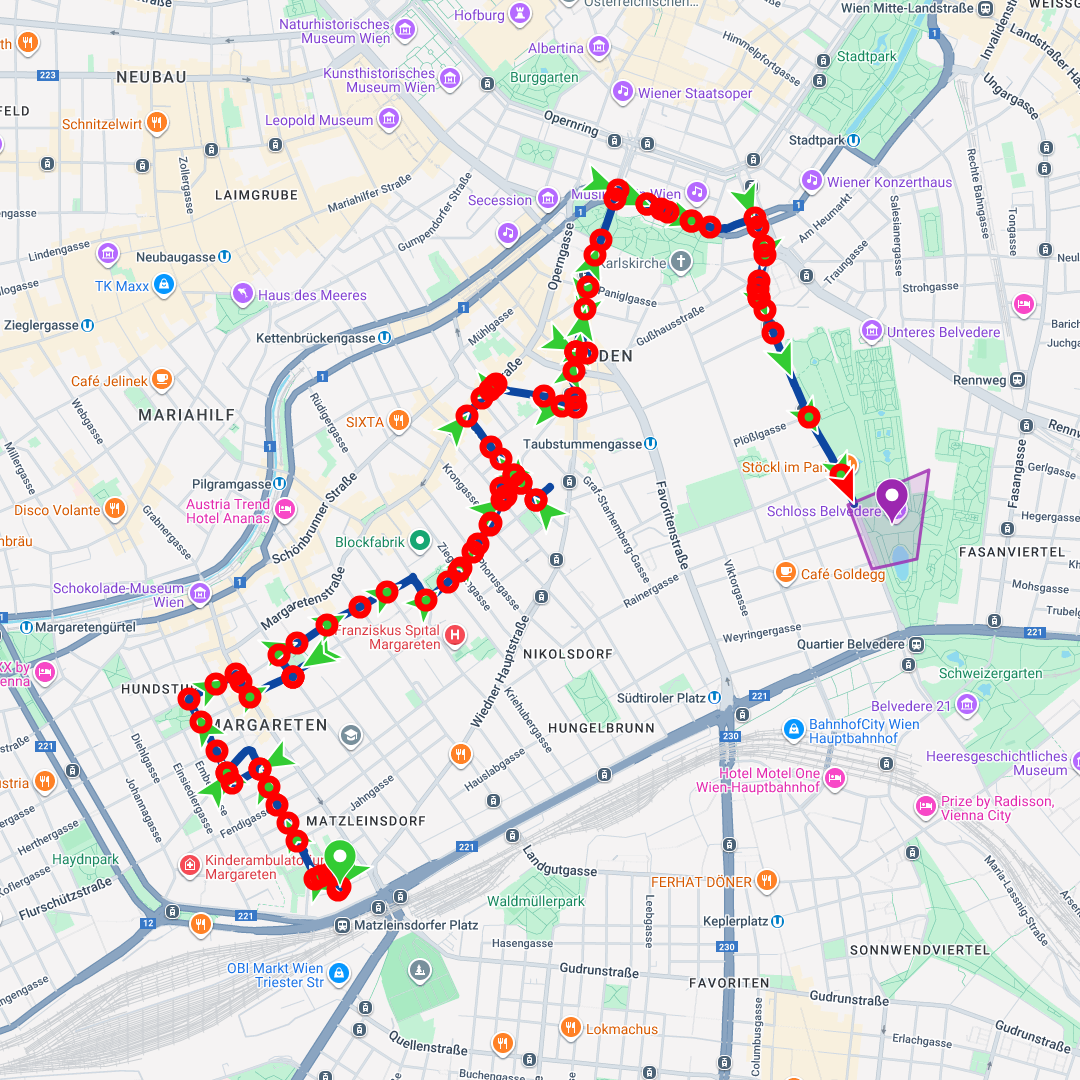
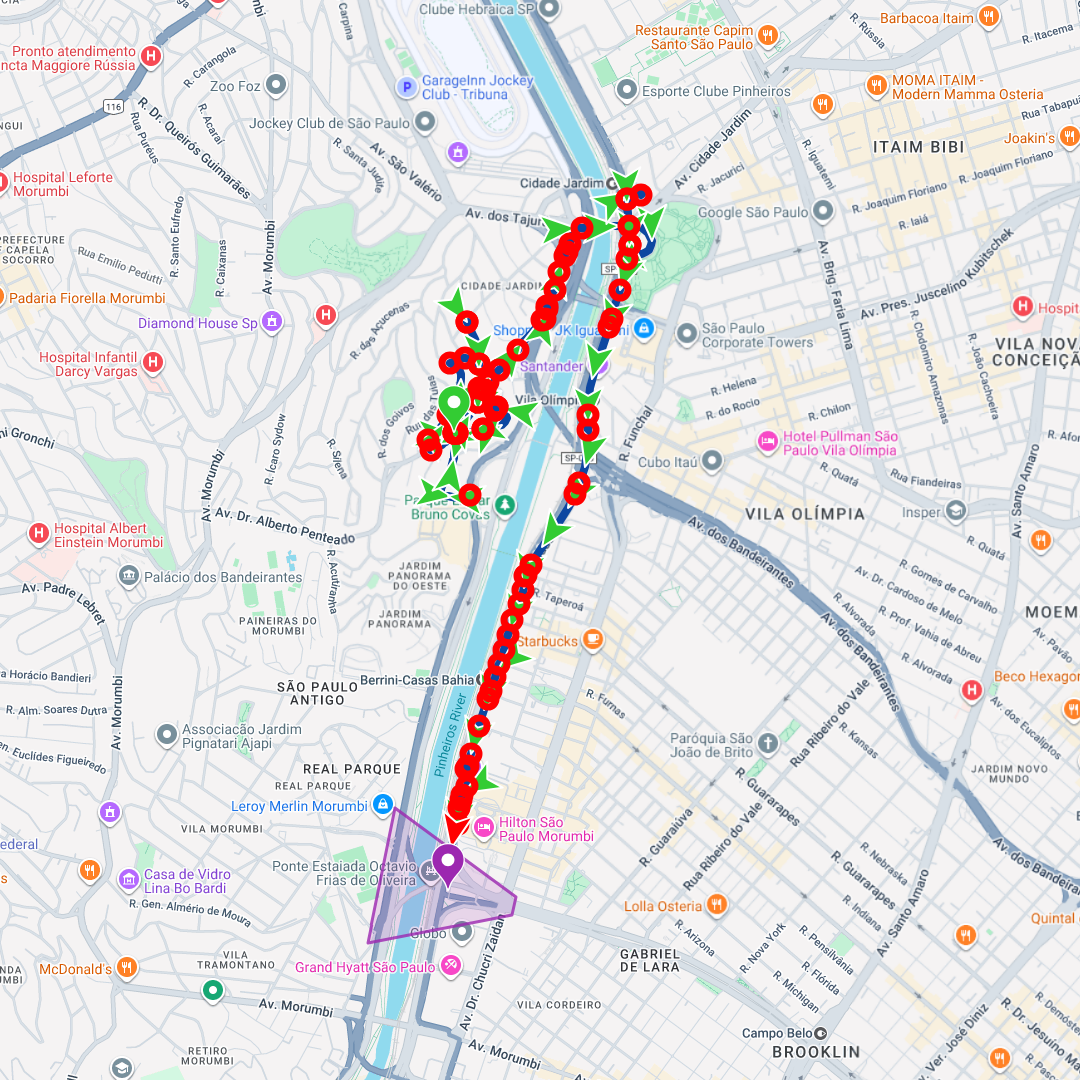
Sample navigation paths. Green markers indicate starting locations and purple polygons mark destination areas.
With Verbalization of Path, GPT-5 reaches 94% navigation success in New York (base model: 54%), 56% in Vienna (11%), 30% in Tokyo (10%), and 29% in São Paulo (7%). GPT-4o rises from 13% to 88% success in New York.
| MLLM | Config | New York | Tokyo | Vienna | São Paulo | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Succ. | SPL | D.A. | Succ. | SPL | D.A. | Succ. | SPL | D.A. | Succ. | SPL | D.A. | ||
| GPT-4o | AgentNav | 88 | 0.539 | 72.9 | 14 | 0.099 | 40.9 | 26 | 0.170 | 46.3 | 20 | 0.06 | 43.5 |
| Base | 13 | 0.064 | 39.0 | 4 | 0.046 | 36.8 | 4 | 0.031 | 35.7 | 3 | 0.040 | 34.7 | |
| GPT-5 | AgentNav | 94 | 0.711 | 83.0 | 30 | 0.163 | 55.0 | 56 | 0.226 | 54.8 | 29 | 0.126 | 49.0 |
| Base | 54 | 0.375 | 56.0 | 10 | 0.088 | 41.2 | 11 | 0.092 | 40.7 | 7 | 0.051 | 37.0 | |
| GPT-4.1 | AgentNav | 92 | 0.557 | 75.3 | 17 | 0.101 | 43.7 | 32 | 0.182 | 50.0 | 22 | 0.080 | 44.1 |
| Base | 15 | 0.097 | 42.3 | 5 | 0.044 | 38.8 | 2 | 0.037 | 34.7 | 5 | 0.049 | 35.5 | |
| Gemini 2.5 | AgentNav | 73 | 0.471 | 74.8 | 17 | 0.066 | 46.9 | 17 | 0.137 | 46.4 | 12 | 0.085 | 43.7 |
| Base | 12 | 0.060 | 41.6 | 8 | 0.049 | 40.0 | 1 | 0.010 | 29.3 | 5 | 0.049 | 35.8 | |
| Qwen 2.5 VL | AgentNav | 32 | 0.153 | 56.4 | 12 | 0.094 | 40.0 | 12 | 0.119 | 44.9 | 9 | 0.059 | 37.8 |
| Base | 7 | 0.089 | 35.1 | 2 | 0.023 | 30.0 | 0 | 0.0 | 26.1 | 2 | 0.011 | 29.9 | |
| Method | New York | Tokyo | Vienna | São Paulo | ||||||||
|---|---|---|---|---|---|---|---|---|---|---|---|---|
| Succ.% | SPL | D.A.% | Succ.% | SPL | D.A.% | Succ.% | SPL | D.A.% | Succ.% | SPL | D.A.% | |
| GPT-4.1 | 15 | 0.097 | 42.3 | 5 | 0.044 | 38.8 | 2 | 0.037 | 34.7 | 5 | 0.049 | 35.5 |
| Chain-of-Thought | 21 | 0.173 | 44.6 | 9 | 0.077 | 41.1 | 4 | 0.039 | 34.9 | 7 | 0.055 | 37.9 |
| Self Reflection (4.1) | 16 | 0.112 | 42.9 | 4 | 0.040 | 36.2 | 3 | 0.042 | 36.3 | 12 | 0.052 | 42.0 |
| Self Reflection (GPT-5) | 22 | 0.168 | 48.1 | 8 | 0.079 | 41.5 | 5 | 0.045 | 37.8 | 13 | 0.050 | 41.6 |
| AgentNav (Ours) | 92 | 0.557 | 75.3 | 17 | 0.101 | 43.7 | 32 | 0.182 | 50.0 | 22 | 0.080 | 44.1 |
@inproceedings{dalal-etal-2026-mllms,
    title = "Can {MLLM}s Find Their Way in a City? Exploring Emergent Navigation from Web-Scale Knowledge",
    author = "Dalal, Dwip  and
      Mishra, Utkarsh  and
      Ahuja, Narendra  and
      Jojic, Nebojsa",
    booktitle = "Proceedings of the 19th Conference of the {E}uropean Chapter of the {A}ssociation for {C}omputational {L}inguistics (Volume 1: Long Papers)",
    month = mar,
    year = "2026",
    address = "Rabat, Morocco",
    publisher = "Association for Computational Linguistics",
    url = "https://aclanthology.org/2026.eacl-long.387/",
    doi = "10.18653/v1/2026.eacl-long.387",
    pages = "8279--8303"
}